Ultimate AI Media Generation Platform
With 843+ top-tier models, A2E is the most powerful platform for AI image and video generation — built to help you create faster and scale without limits.
Genjutsu-style object swap: change hair, clothes or the whole background in a video by naming it, keeping the rest of the shot and the original audio.
Genjutsu-style character swap: replace people in a video with characters from your pictures, keeping the scene, motion and original audio.
Wan 2.2 Animate 2 is the next-generation Wan character animation model: an end-to-end DiT that makes the character in a reference image perform the motion of a driving video, with no pose extraction, prompt-controlled background, and strong identity preservation; generates 480p/720p videos up to 120s. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
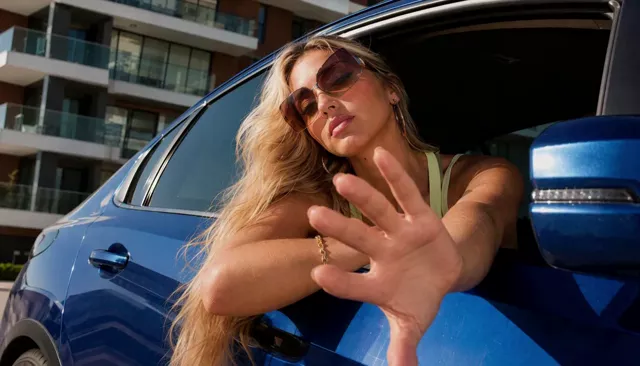
Open-weights MiniMax H3 reference-to-video: generate coherent 480p/540p/768p/1080p videos with native stereo audio guided by up to 9 reference images, 3 reference videos, and 3 reference audios.
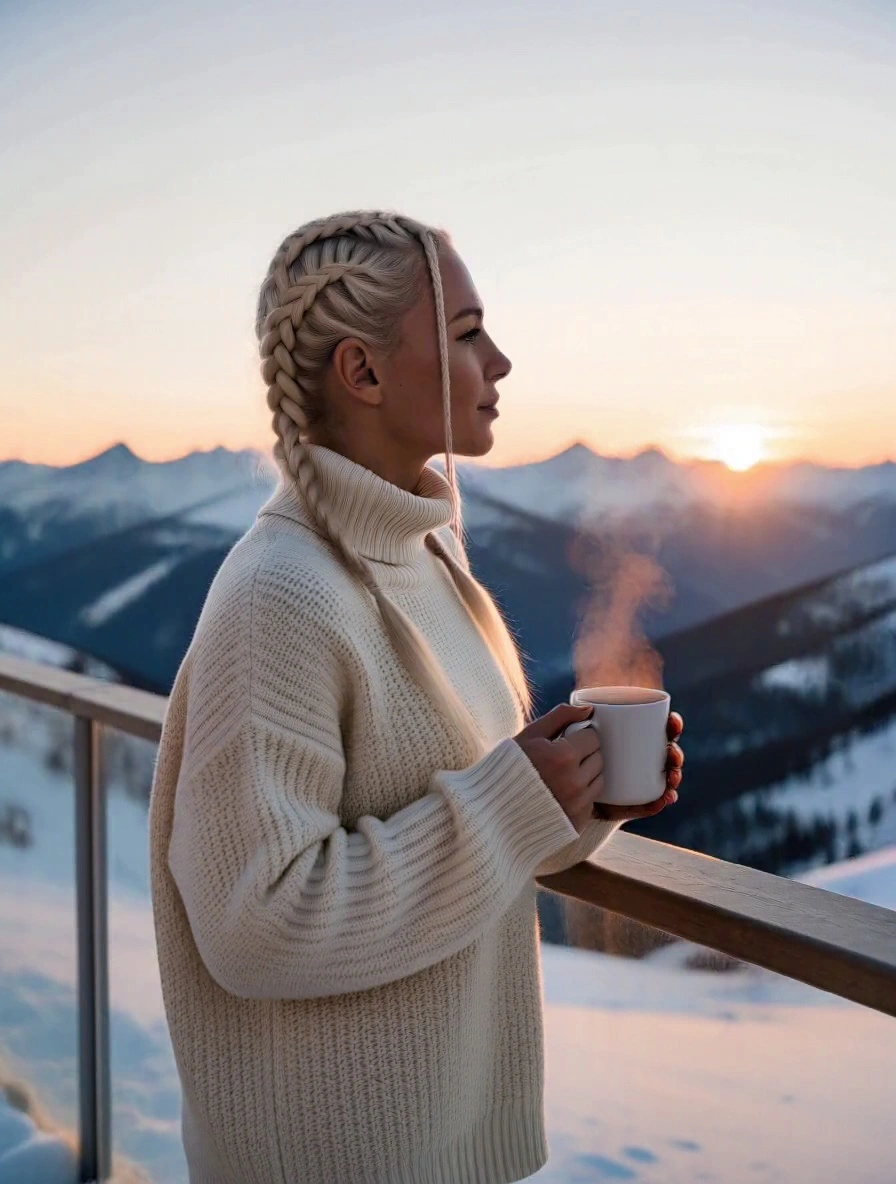
MiniMax H3 Open Weights Image Edit re-renders a subject from up to 9 reference images into a new scene, outfit or style from a text instruction, preserving identity at 1K or 2K resolution. Loads up to 3 custom LoRA weights per request. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
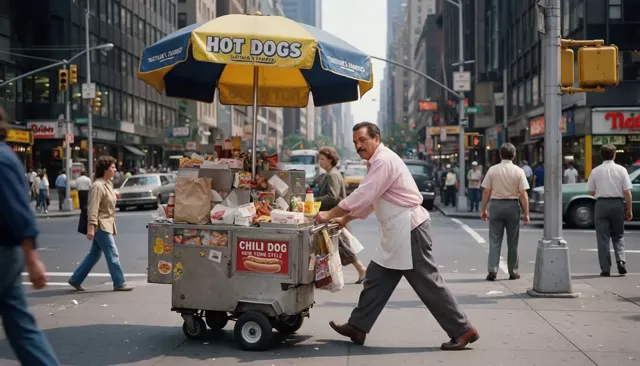
Open-weights MiniMax H3 Singularity reference-to-video: generate coherent 480p/540p/768p/1080p videos with native stereo audio guided by up to 9 reference images, 3 reference videos, and 3 reference audios.
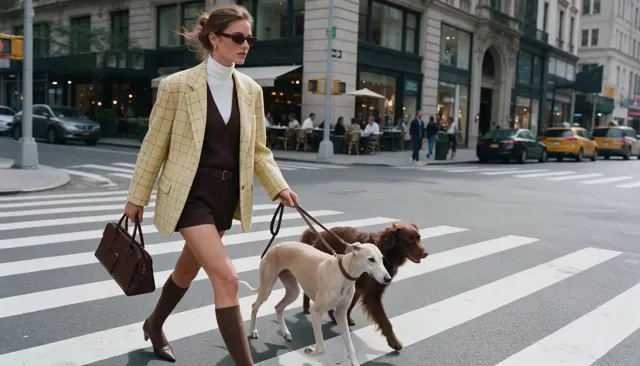
Open-weights MiniMax H3 Singularity reference-to-video: generate coherent 480p/540p/768p/1080p videos with native stereo audio guided by up to 9 reference images, 3 reference videos, and 3 reference audios, with custom LoRA support.
Open-weights MiniMax H3 Singularity image-to-video: animate a first-frame image (optionally with a last frame) into a coherent 480p/540p/768p/1080p video with native stereo audio, 5-15 second durations, and affordable per-second pricing.
Open-weights MiniMax H3 text-to-video: coherent 480p/540p/768p/1080p videos with native stereo audio from a single prompt, 5-15 second durations, flexible aspect ratios, and affordable per-second pricing.
Open-weights MiniMax H3 image-to-video: animate a first-frame image (optionally with a last frame) into a coherent 480p/540p/768p/1080p video with native stereo audio, 5-15 second durations, and affordable per-second pricing.
Open-weights MiniMax H3 Singularity image-to-video: animate a first-frame image (optionally with a last frame) into a coherent 480p/540p/768p/1080p video with native stereo audio, 5-15 second durations, and affordable per-second pricing, with custom LoRA support.
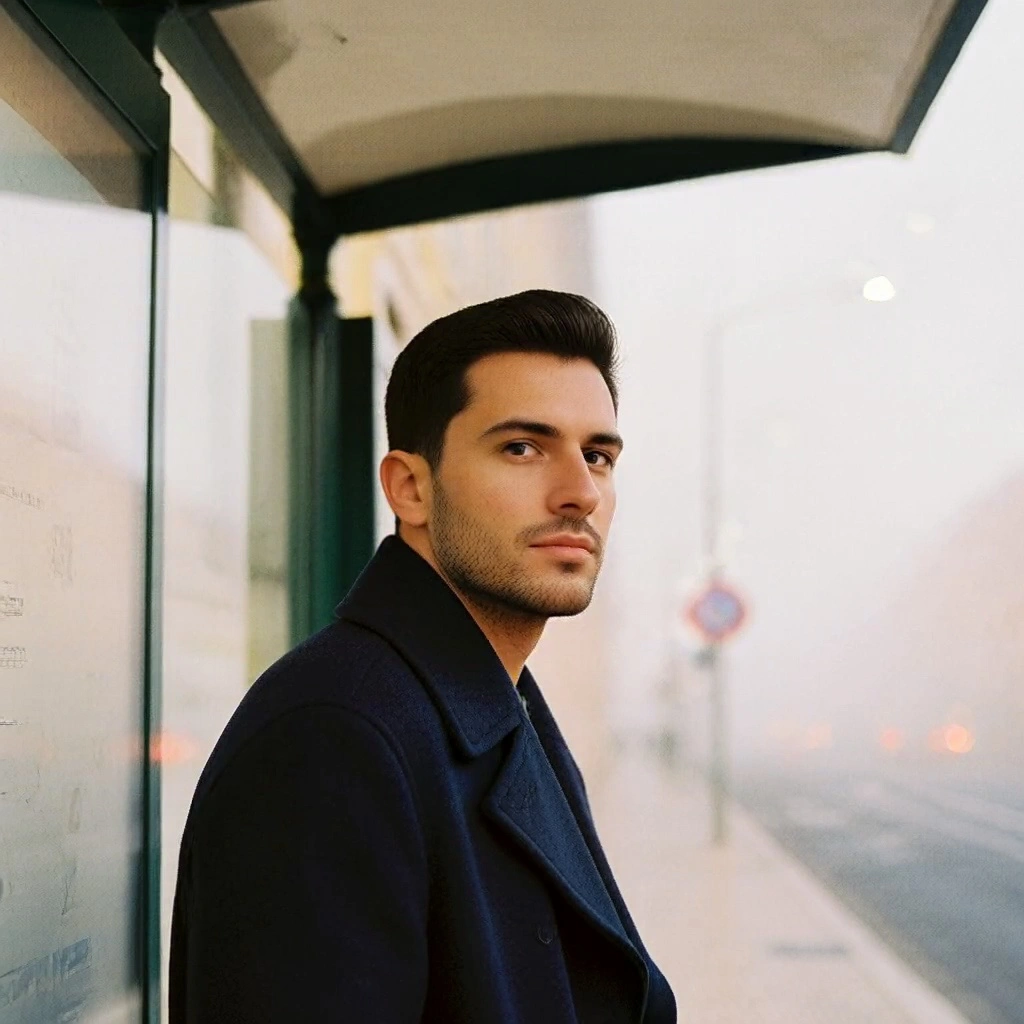
MiniMax H3 Open Weights Text-to-Image generates photorealistic, cinema-grade stills from a text prompt at 1K or 2K resolution with a wide choice of aspect ratios. Loads up to 3 custom LoRA weights per request. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
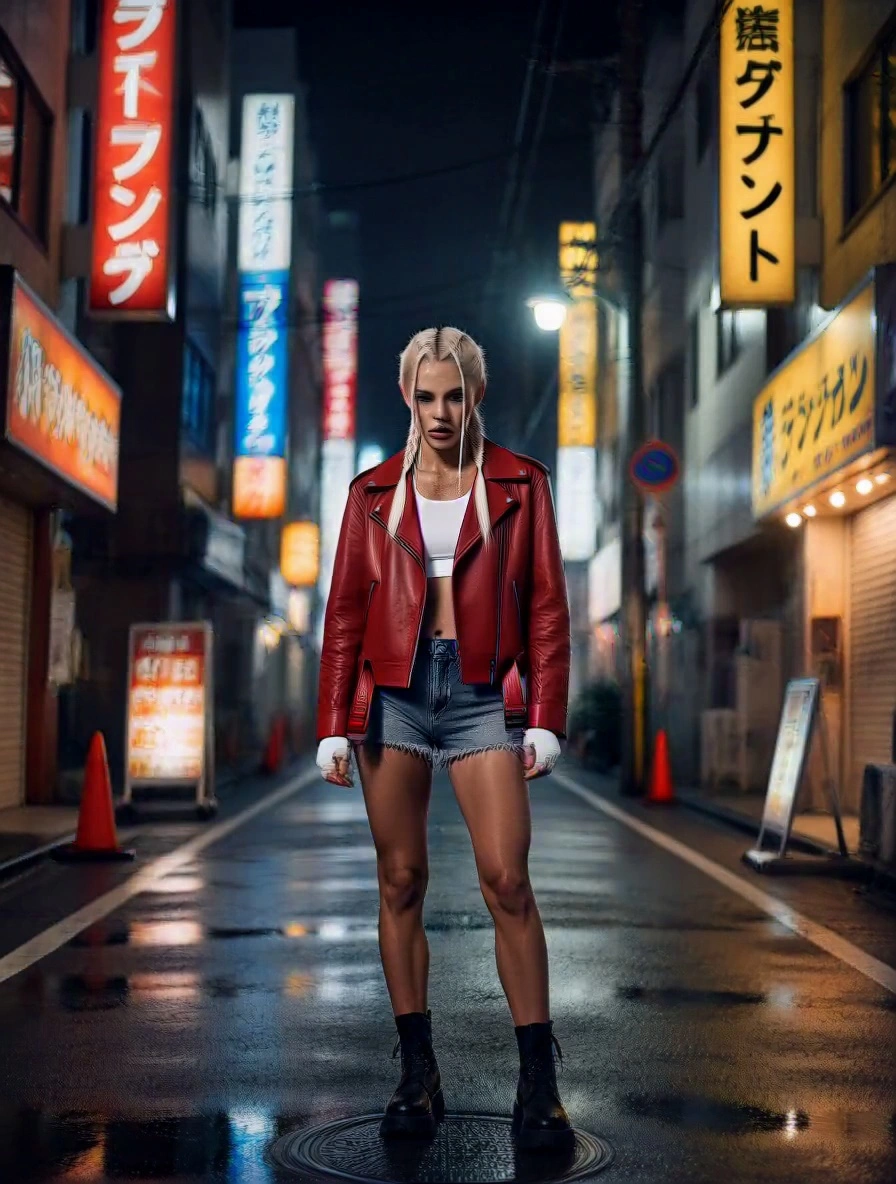
MiniMax H3 Open Weights Image Edit re-renders a subject from up to 9 reference images into a new scene, outfit or style from a text instruction, preserving identity at 1K or 2K resolution. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
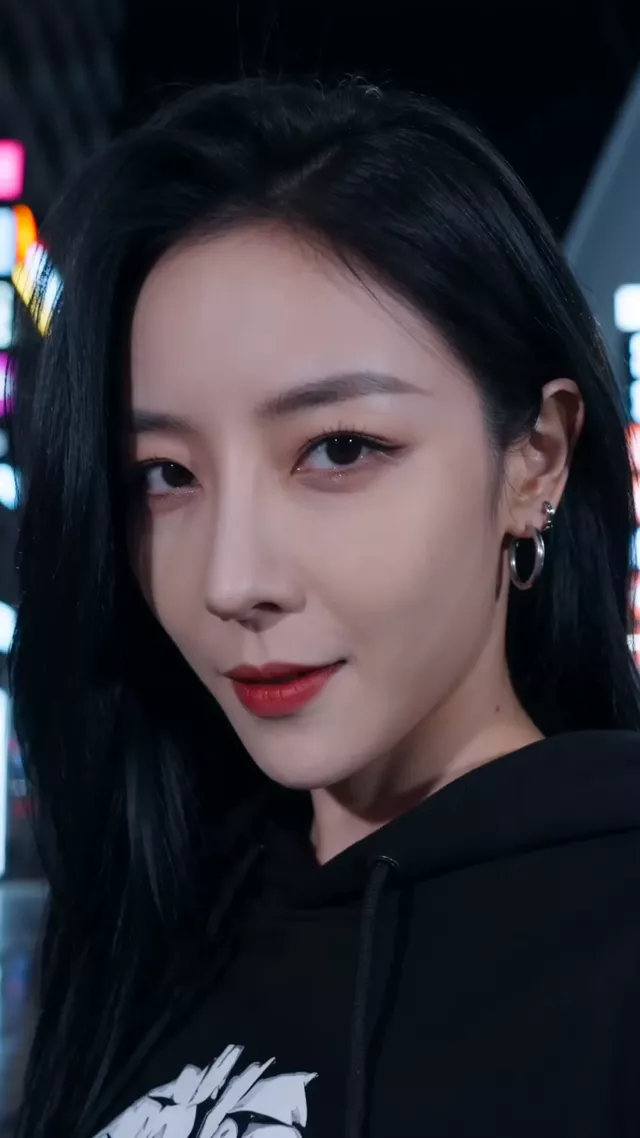
MiniMax H3 Open Weights ControlNet Union generates a new video that follows the motion and composition of a source video. Pose, depth, edges, lines, scribble or grayscale structure is extracted from the source automatically and guides the output, optionally with reference images for the subject or style, with native stereo audio generated in the same pass. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
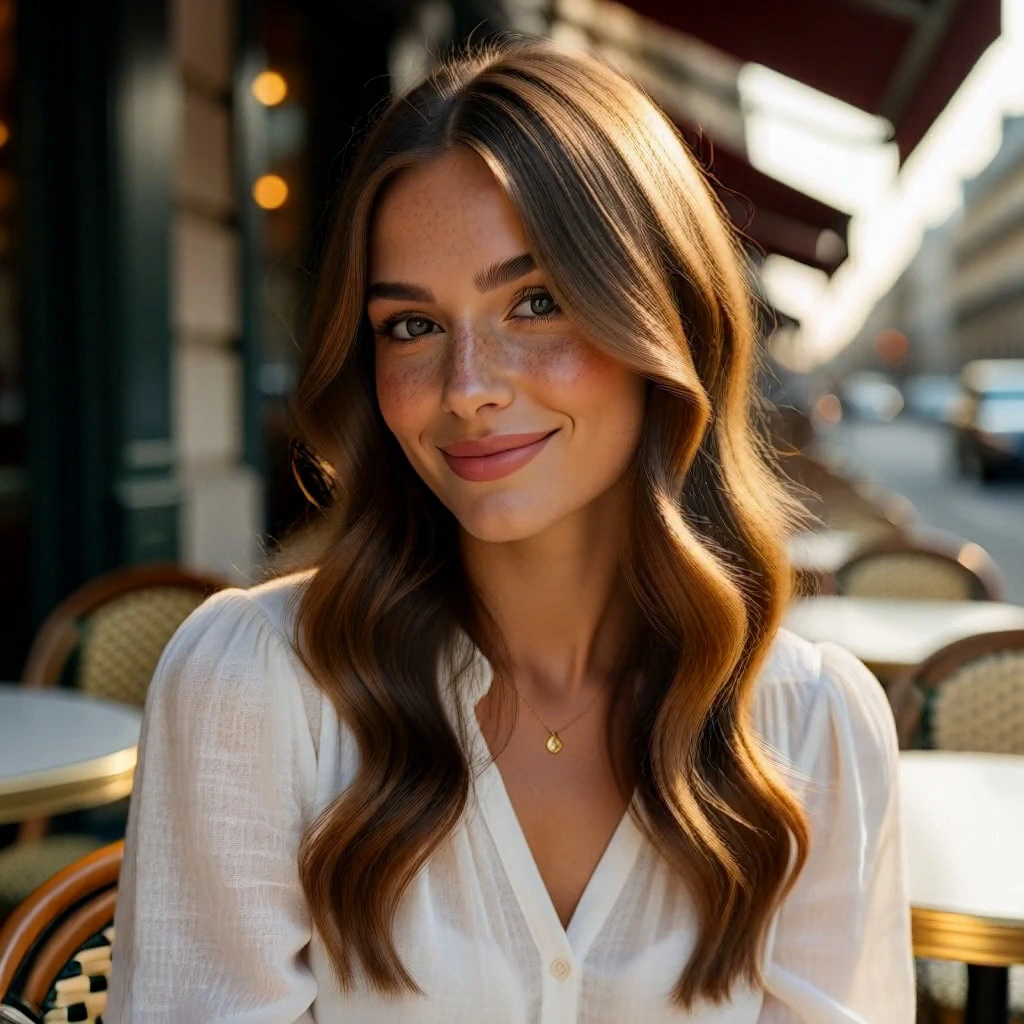
MiniMax H3 Open Weights Text-to-Image generates photorealistic, cinema-grade stills from a text prompt at 1K or 2K resolution with a wide choice of aspect ratios. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
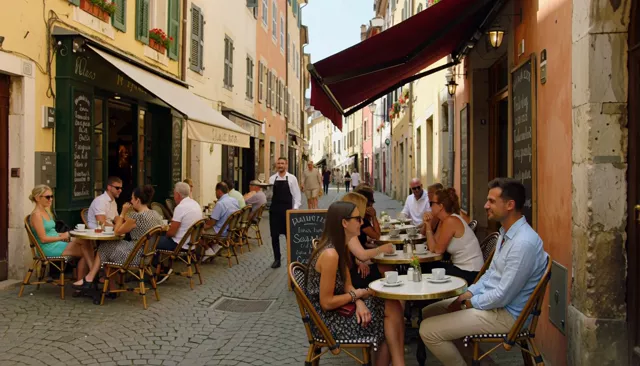
MiniMax H3 Open Weights Video-Edit edits an input video from a natural-language prompt. The input video drives subject identity, composition, and motion while the model rewrites lighting, style, weather, environment, or specific elements as instructed, with native stereo audio generated in the same pass.
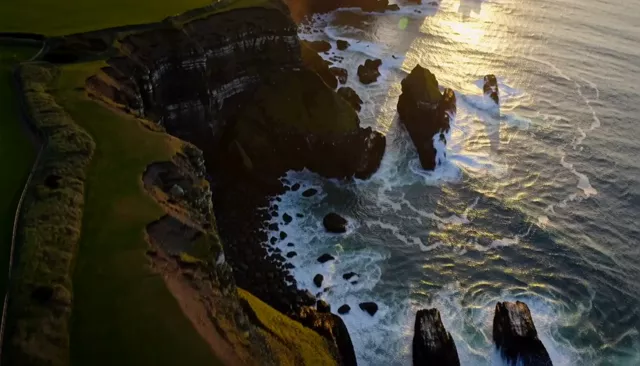
MiniMax H3 Open Weights Video-Extend appends a new cinematic continuation to an existing video. A fresh segment with native stereo audio is generated from the input video's last frame and a natural-language prompt, then concatenated onto the original.
Open-weights MiniMax H3 reference-to-video: generate coherent 480p/540p/768p/1080p videos with native stereo audio guided by up to 9 reference images, 3 reference videos, and 3 reference audios, with custom LoRA support.
Open-weights MiniMax H3 image-to-video: animate a first-frame image (optionally with a last frame) into a coherent 480p/540p/768p/1080p video with native stereo audio, 5-15 second durations, and affordable per-second pricing, with custom LoRA support.
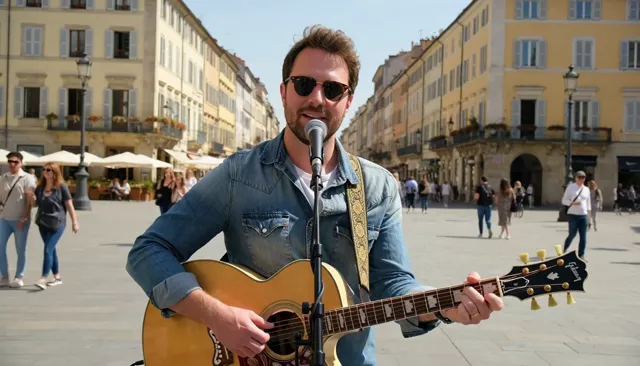
Open-weights MiniMax H3 text-to-video: coherent 480p/540p/768p/1080p videos with native stereo audio from a single prompt, 5-15 second durations, flexible aspect ratios, and affordable per-second pricing, with custom LoRA support.
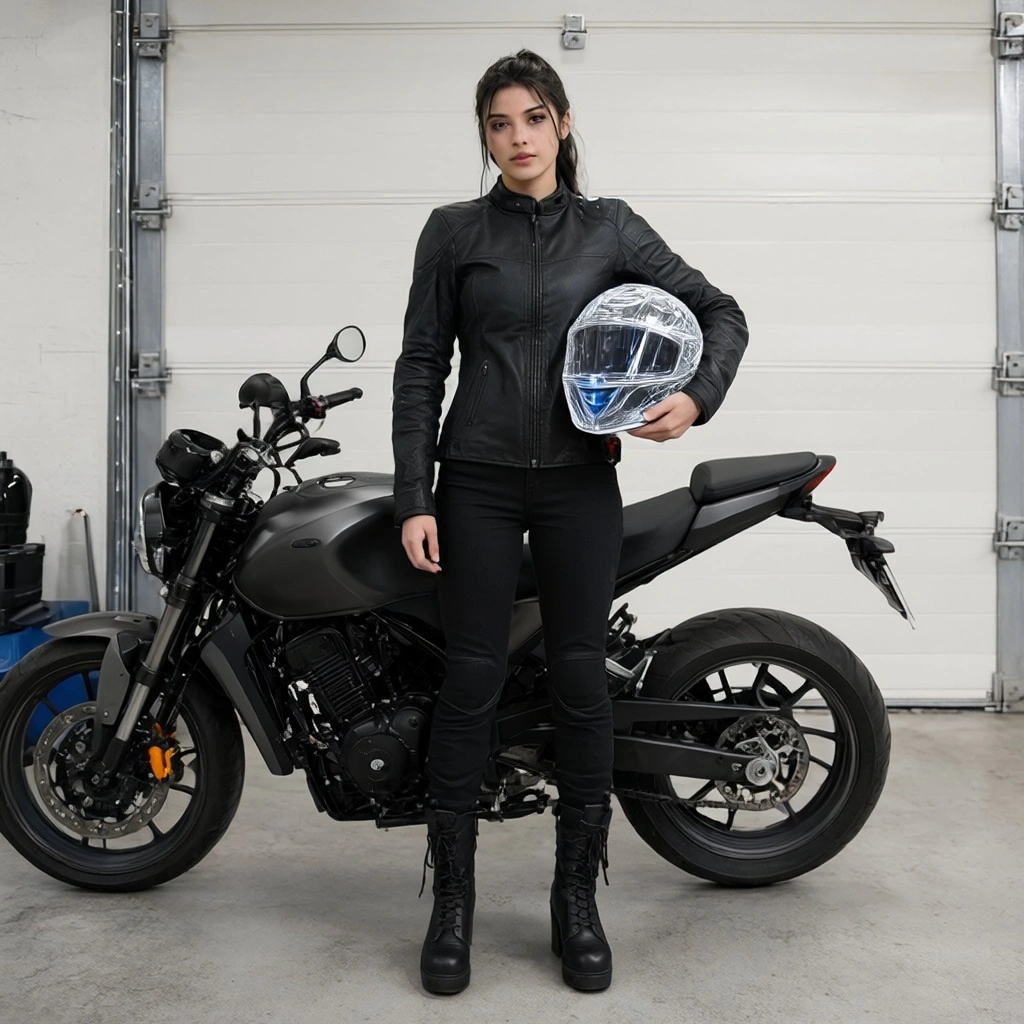
P-H3-Image by Pruna AI, built on the MiniMax H3 open weights, edits an image from a text instruction with up to 8 extra reference images, keeping faces, products and details consistent, at 1K to 4K resolution. Loads up to 3 custom LoRA weights per request. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
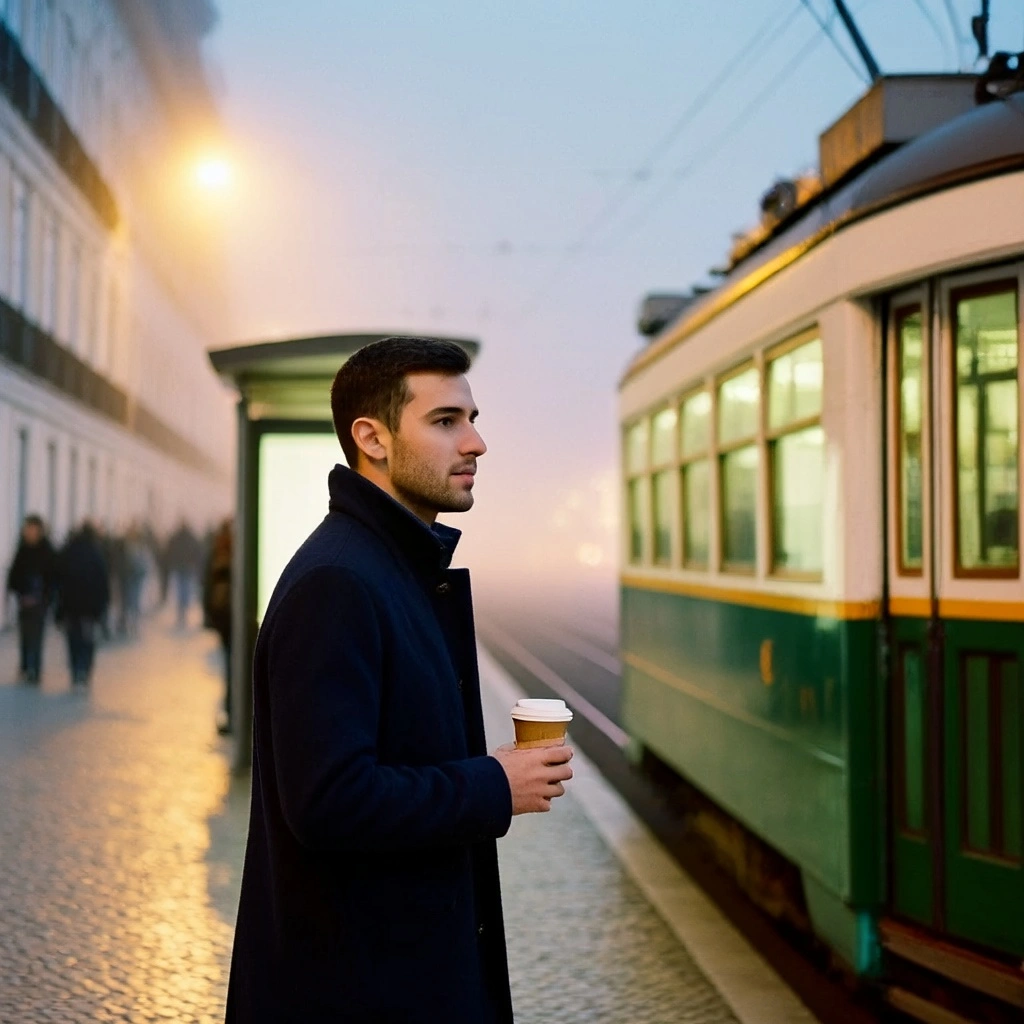
P-H3-Image by Pruna AI, built on the MiniMax H3 open weights, turns a text prompt into a photorealistic, editorial-quality image, at 1K to 4K resolution. Loads up to 3 custom LoRA weights per request. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
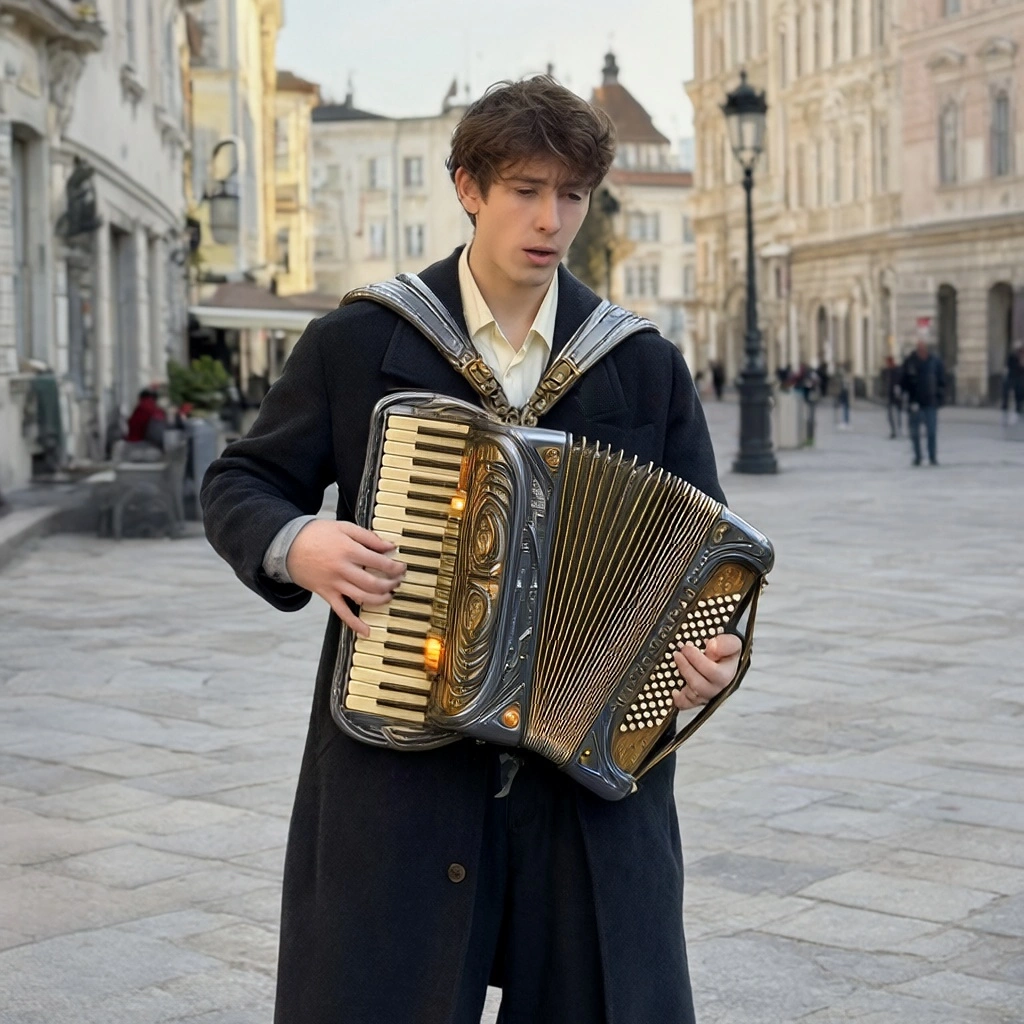
P-H3-Image by Pruna AI, built on the MiniMax H3 open weights, edits an image from a text instruction with up to 8 extra reference images, keeping faces, products and details consistent, at 1K to 4K resolution. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
P-H3-Image by Pruna AI, built on the MiniMax H3 open weights, turns a text prompt into a photorealistic, editorial-quality image, at 1K to 4K resolution. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
InfiniteTalk Multi converts a single image and two audio inputs into multi-character talking or singing videos at up to 720p. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
InfiniteTalk converts one photo + audio into audio-driven talking or singing avatar videos (Image-to-Video), up to 10 minutes, 720p tier $0.30/5s. Ready-to-use REST API, no coldstarts, affordable pricing.
Krea 2 Turbo is Krea's 12.9B open-weights diffusion transformer distilled to 8 steps, generating aesthetic-first images natively at 1K to 2K resolution in seconds, with both text-to-image and image-to-image supported. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Krea 2 Turbo with LoRA support runs custom LoRAs (trained on Krea 2 Raw, comfy or diffusers naming) on the 8-step distilled Krea 2 engine, generating personalized images natively at 1K to 2K resolution, with both text-to-image and image-to-image supported. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Anima is CircleStone Labs' 2B anime text-to-image model (Cosmos-Predict2 DiT with a Qwen3 text encoder), distilled to 8-12 steps and generating tag-driven anime illustrations natively at 1K to 1.5K resolution in seconds, with both text-to-image and image-to-image supported. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Anima with LoRA support runs custom character and style LoRAs on CircleStone Labs' 2B anime model, generating personalized anime illustrations natively at 1K to 1.5K resolution, with both text-to-image and image-to-image supported. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Krea 2 Medium Text to Image generates high-quality images from text prompts with aspect ratio, creativity, and optional style reference controls.
MOSS Image Text-to-Image generates images from long text prompts, with sharp Chinese and English text rendering, 1K or 2K output and flexible aspect ratios.
MOSS Image Text-to-Image LoRA generates images from long text prompts with up to 3 custom LoRAs, sharp Chinese and English text rendering, 1K, 1.5K or 2K output and flexible aspect ratios.
Krea 2 Large Text to Image generates high-fidelity images from text prompts with aspect ratio, creativity, and optional style reference controls.
OpenVideo image-to-video (LoRA tier) — full creative control over short cinematic clips with a native audio track, plus an optional preset and per-LoRA strength dict to drive style, motion and look-and-feel. Unlimited generation freedom on the same base model as the standard endpoint. Supports 480p / 720p / 1080p output and 3-20 s duration.
OpenVideo image-to-video gives you full creative control over short cinematic clips with a native audio track. Unlimited generation freedom — describe any scene, style or motion and the model follows the prompt as-given, from a single reference image. Supports 480p / 720p / 1080p output and 3-20 s duration tiers.
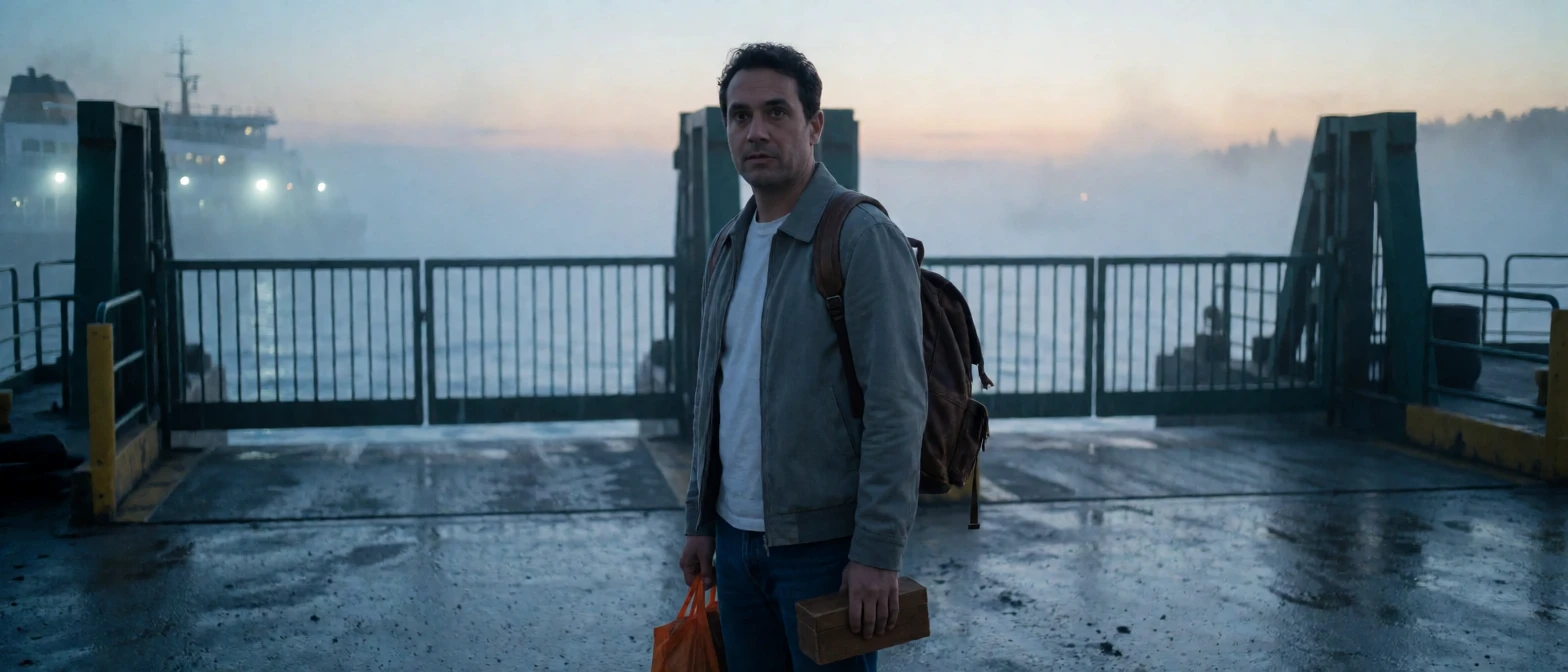
Krea 2 Medium Turbo Text to Image generates fast, high-quality images from text prompts with aspect ratio, creativity, and optional style reference controls.
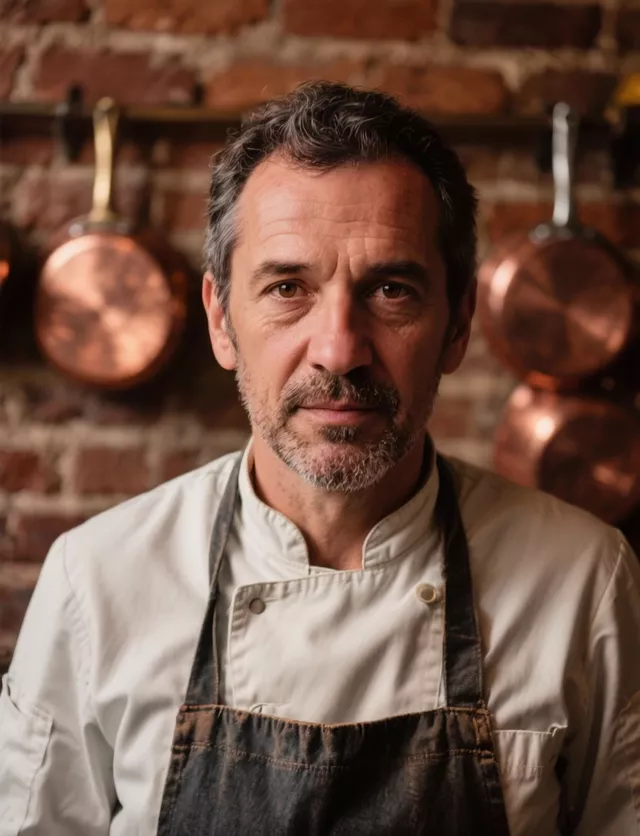
Audio-driven InfiniteTalk turns one video plus audio into realistic talking or singing videos with lip-sync in 480p or 720p. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
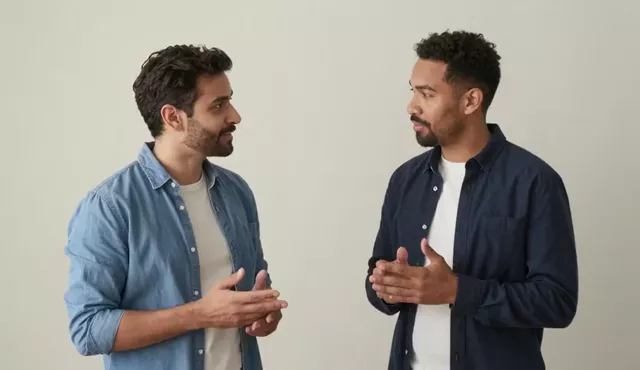
LongCat Avatar 1.5 Multi converts a single image and two audio inputs into multi-character talking or singing videos at up to 720p, capped at 64 seconds per clip. Ready-to-use REST API, no coldstarts, affordable pricing.
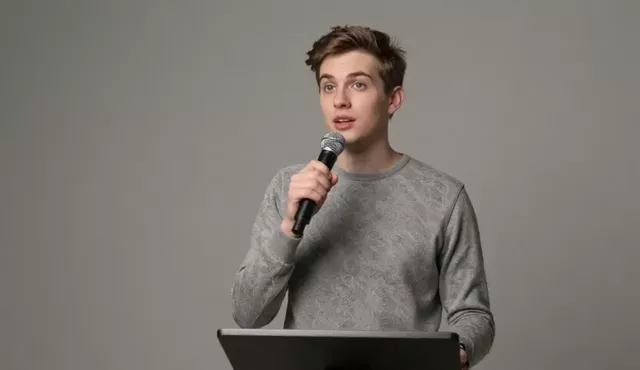
LongCat Avatar 1.5 is the upgraded version of LongCat Avatar with sharper lip sync and faster generation. Converts one photo + audio into audio-driven talking or singing avatar videos (Image-to-Video), capped at 64 seconds per clip. Ready-to-use REST API, no coldstarts, affordable pricing.