Ultimate AI Media Generation Platform
With 882+ top-tier models, A2E is the most powerful platform for AI image and video generation — built to help you create faster and scale without limits.
Gemini Omni 1.2 Flash Text-to-Video creates short videos with synchronized audio from a text prompt.
Gemini Omni 1.2 Flash Reference-to-Video creates synchronized audiovisual clips from a prompt and optional image or video references.
Seedance 2.5 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on ByteDance Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive, physically accurate motion.
Seedance 2.5 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on ByteDance Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Seedance 2.5 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on ByteDance Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Seedance 2.5 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images and text prompts —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability. Built on ByteDance Seed's unified multimodal architecture.
Seedance 2.5 (Text-to-Video Turbo) generates cinematic videos from text prompts at 720p and 1080p with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability — optimized for turbo output. Built on ByteDance Seed's unified multimodal architecture. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Seedance 2.5 (Text-to-Video Turbo) generates cinematic videos from text prompts at 720p and 1080p with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability — optimized for turbo output. Built on ByteDance Seed's unified multimodal architecture. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Kling V4.0 Reference-to-Video builds a new clip of 3 to 30 seconds from up to 10 reference images, 5 reference videos and 3 reference audios, following the subjects, motion and camera you point to in the prompt, with 720p and 1080p output and synchronized stereo audio. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Kling V4.0 Image-to-Video animates a first frame into a clip of 3 to 30 seconds, with an optional last frame and up to 8 in-between keyframes to direct the story, 720p and 1080p output and synchronized stereo audio. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Kling V4.0 Video Edit rewrites a 3 to 30 second video from a text instruction: it keeps the scene, subject and motion and changes what you describe, with optional reference images and audios, 720p and 1080p output and new synchronized audio generated by default (the original sound can be kept instead). Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Kling V4.0 Video Extend continues a video from its last frame with a new 3 to 30 second segment guided by your prompt, at 720p or 1080p with synchronized stereo audio, and returns the original and the new segment joined. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Kling V4.0 Text-to-Video generates cinematic clips of 3 to 30 seconds from a text prompt, with 720p and 1080p output, four aspect ratios including 21:9 ultrawide, and synchronized stereo audio. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Kling V4.0 Flash Text-to-Video generates 3 to 20 second 720p clips from a text prompt with synchronized audio, in four aspect ratios including 21:9 ultrawide; Flash is the fast, lower-cost tier of Kling 4.0 for quick iteration. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Kling V4.0 Flash Image-to-Video animates a first-frame image into a 3 to 20 second 720p clip with synchronized audio; Flash is the fast, lower-cost tier of Kling 4.0 for quick iteration. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Kling V4.0 Flash Reference-to-Video generates a 3 to 20 second 720p clip guided by up to 10 reference images and 5 reference videos, with synchronized audio; Flash is the fast, lower-cost tier of Kling 4.0. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Kling V4.0 Flash Video Edit rewrites a 3 to 20 second video from a text instruction at 720p: it keeps the scene, subject and motion and changes what you describe, with optional reference images and new synchronized audio by default. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Gemini Omni 1.1 Flash Reference-to-Video creates synchronized audiovisual clips from a prompt and optional image or video references.
Gemini Omni 1.1 Flash Text-to-Video creates short videos with synchronized audio from a text prompt.
Gemini Omni Flash Text-to-Video creates short videos with synchronized audio from a text prompt.
HeyGen Avatar V Digital Twin generates natural avatar videos from text or audio with lip-sync, optional captions, background removal, and MP4/WebM output.
Seedance 2.0 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on ByteDance Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive, physically accurate motion.
Seedance 2.0 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on ByteDance Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Seedance 2.0 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on ByteDance Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Seedance 2.0 Fast (Image-to-Video) generates cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level control, and exceptional motion stability — optimized for faster generation. Built on ByteDance Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive motion.
Seedance 2.0 Fast (Text-to-Video) generates cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability — optimized for faster generation. Built on ByteDance Seed's unified multimodal architecture. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Seedance 2.0 Fast (Text-to-Video) generates cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability — optimized for faster generation. Built on ByteDance Seed's unified multimodal architecture. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
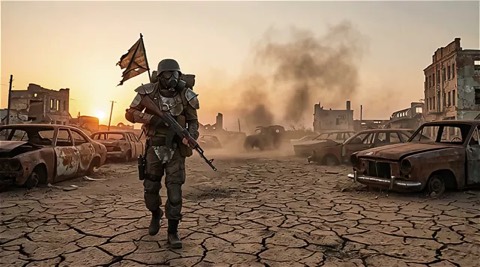
Alibaba WAN 2.6 converts text or images into videos (720p/1080p) with synced audio, faster and more affordable than Google Veo3. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
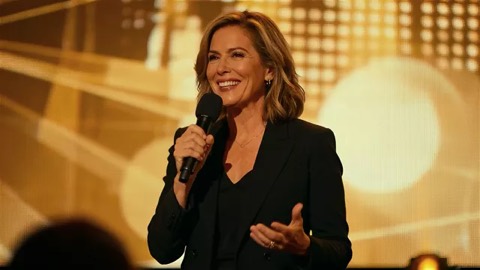
Alibaba WAN 2.5 converts text or images into videos (480p/720p/1080p) with synced audio, faster and more affordable than Google Veo3. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
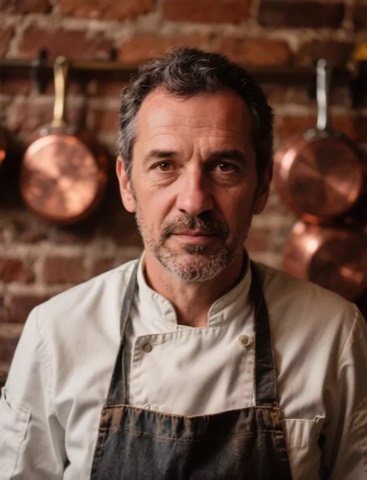
Audio-driven InfiniteTalk turns one video plus audio into realistic talking or singing videos with lip-sync in 480p or 720p. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
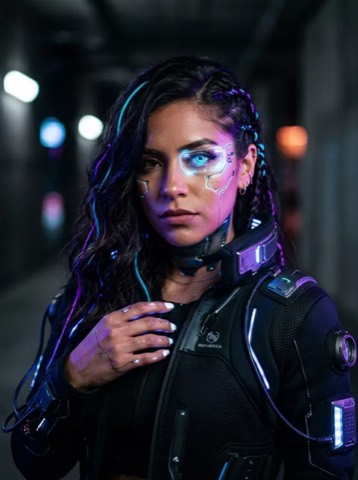
Sync Lipsync 3 Avatar turns a still image into a talking character video driven by an input audio track.
Seedance 2.0 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images and text prompts —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability. Built on ByteDance Seed's unified multimodal architecture.
Seedance 2.0 (Text-to-Video Turbo) generates cinematic videos from text prompts at 720p and 1080p with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability — optimized for turbo output. Built on ByteDance Seed's unified multimodal architecture. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Seedance 2.0 (Text-to-Video Turbo) generates cinematic videos from text prompts at 720p and 1080p with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability — optimized for turbo output. Built on ByteDance Seed's unified multimodal architecture. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Google Veo 3.1 converts text prompts into videos with synchronized audio at native 1080p for high-quality outputs. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Seedance 2.0 Fast (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images and text prompts using speed-optimized inference —the fastest Seedance image-to-video option with native audio-visual synchronization, director-level control, and exceptional motion stability. Built on ByteDance Seed's unified multimodal architecture.
Seedance 2.0 Fast (Text-to-Video Turbo) generates cinematic 720p/1080p videos from text prompts using speed-optimized inference —the fastest Seedance option with native audio-visual synchronization, director-level control, and exceptional motion stability. Built on ByteDance Seed's unified multimodal architecture. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Seedance 2.0 Fast (Text-to-Video Turbo) generates cinematic 720p/1080p videos from text prompts using speed-optimized inference —the fastest Seedance option with native audio-visual synchronization, director-level control, and exceptional motion stability. Built on ByteDance Seed's unified multimodal architecture. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Alibaba WAN 2.6 Video-Extend turns short clips into longer videos with preserved or generated synchronized audio for continuity. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
Alibaba WAN 2.5 Fast converts text or images into synchronized-audio videos in 480p, 720p, or 1080p, offering faster, more affordable generation compared to Google Veo3. REST API, no coldstarts, affordable pricing.